
Saturday 29 March 2025
The quest for better recommendations has been a longstanding challenge in the world of online content consumption. From music streaming services to e-commerce platforms, personalized suggestions have become an essential feature in modern digital life. However, traditional recommendation systems often rely on simplistic approaches that fail to capture the complexities of user behavior and item characteristics.
In recent years, researchers have turned to deep learning techniques to improve the accuracy of recommender systems. One such approach is the use of semantic tokens, which aim to represent items as a combination of unique attributes and shared patterns. However, this method has its limitations, particularly when it comes to capturing the nuanced relationships between users and items.
Enter a new study from a team of researchers who have proposed a novel framework that unifies ID tokens and semantic tokens in a single representation learning model. The idea is simple yet powerful: by combining the strengths of both approaches, the resulting model can better capture the unique characteristics of each item while also taking into account the shared patterns that emerge across different items.
The researchers’ approach begins with the creation of a codebook, which serves as a dictionary of semantic tokens. Each token in the codebook corresponds to a specific attribute or pattern, and is learned through a process called residual quantization. The ID tokens, on the other hand, are used to capture the unique characteristics of each item.
The key innovation lies in how the two types of tokens are combined. The researchers use a technique called cosine similarity to decouple the accumulated embeddings from the unique items, allowing for more accurate recommendations. Meanwhile, Euclidean distance is employed to distinguish between items with similar characteristics.
Experiments conducted on three real-world datasets demonstrate the effectiveness of this approach. Compared to traditional methods, the unified framework achieves significant improvements in performance, with accuracy gains ranging from 6% to 17%. Moreover, the reduction in token size by over 80% offers a substantial boost in computational efficiency.
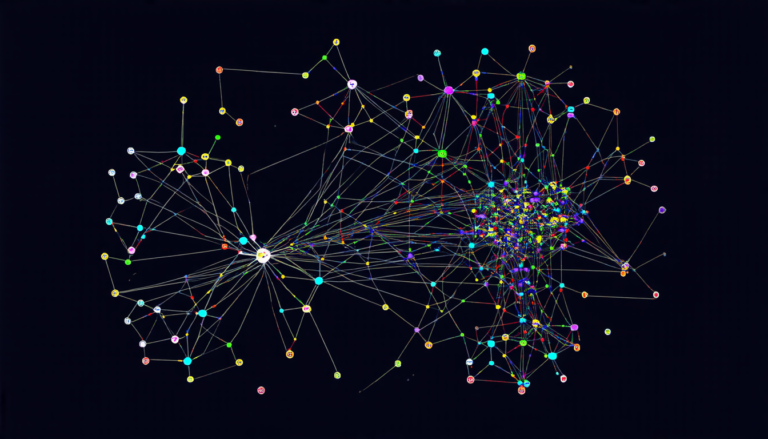
The researchers also provide insight into the behavior of their model through visualization techniques. By examining the patterns of codebooks across different layers, they reveal that the model is able to capture both unique and shared item characteristics with remarkable accuracy.
While this study offers exciting prospects for improving recommender systems, there are still challenges to be addressed. For instance, the authors acknowledge that the degeneration problem in codebook size may limit the scalability of their approach. Nevertheless, the results presented here provide a compelling case for the potential of unified representation learning in recommender systems.
Cite this article: “Unifying ID and Semantic Tokens for Improved Recommender Systems”, The Science Archive, 2025.
Recommender Systems, Deep Learning, Semantic Tokens, Id Tokens, Codebook, Residual Quantization, Cosine Similarity, Euclidean Distance, Computational Efficiency, Scalability